A hotel loses internet access during check-in. Guests can't authenticate to WiFi, card terminals start timing out, staff lose access to cloud systems, and reception begins handing out a shared password that nobody can revoke. The backup circuit exists, but the firewall policy was never tested. The second RADIUS server is configured, but no one knows whether the access points will reach it. The UPS is reporting healthy because nobody has checked the battery under load.
That isn't a hardware problem. It's a redundancy planning failure.
Network resilience means keeping authentication, connectivity, and essential services available when a component, link, site, power feed, or identity dependency fails. A spare switch in a closet doesn't create resilience. A tested path that keeps a payment VLAN, clinical application, staff login, or guest WiFi session working does.
What Redundancy Planning Actually Means for Modern Networks
Network redundancy planning is a business continuity discipline, not an equipment purchasing exercise. The question isn't whether you own two switches. It's whether users can still connect, authenticate, resolve services, and reach the applications that keep the operation running after a defined failure.
That requires a clear view of failure domains. A failure domain is a component or dependency that can fail independently and take a service with it. Typical domains include:
- Access infrastructure, including switches, access points, PoE budgets, uplinks, and wireless controllers.
- Identity services, including RADIUS, directory integrations, certificates, captive portals, and identity providers.
- Core services, including DHCP, DNS, gateway functions, and network policy.
- External paths, including WAN circuits, ISP equipment, cloud platforms, and third-party authentication services.
- Facilities, including power distribution, UPS batteries, generator coverage, and telecommunications closets.
A design can have resilient core routers and still fail at the edge. If DNS resolution stops, users may be connected to WiFi but unable to reach the services they need. If RADIUS stops responding, a healthy wireless network can reject every staff or guest login. If the captive portal depends on one unreachable cloud path, the venue may have radio coverage without usable guest access.
Separate service continuity from component redundancy
Start with services, not devices. Write down the services the business must preserve, then trace every dependency beneath each one. Guest WiFi authentication, for example, may depend on access points, switching, PoE, the wireless control plane, DHCP, DNS, WAN access, RADIUS, the identity provider, and the portal itself.
A useful network team WiFi planning reference should lead to the same conclusion: wireless access is an operational system, not a radio layer bolted onto the LAN.
Employers in the United States use a separate statutory meaning of collective redundancy planning under the WARN Act. Where an employer proposes to lay off large groups of workers, statutory notice periods and state-level mini-WARN Acts apply. That is an HR planning framework. The network discipline described here concerns service failure, dependency mapping, and recovery architecture.
Practical rule: Don't count backup devices. Count independent paths from the user to the service.
The rest of this guide uses that practical lens. Identify the failure risks, set recovery targets that reflect business pain, select an architecture that your team can operate, protect every layer from power to identity, and test the result under controlled conditions. If a component has never failed in a drill, treat its redundancy as an assumption, not a capability.
Mapping Failure Risks Before You Design the Fix
Most network teams don't need a governance platform to find their most dangerous single points of failure. They need a short register that names the risk, ranks it consistently, assigns an owner, and records whether anyone has reduced it.
Use three axes:
- Likelihood, meaning how often the failure occurs in comparable properties or has occurred in your own environment.
- Blast radius, meaning how many users, sites, services, or revenue-producing activities become unavailable.
- Recovery pain, meaning how difficult restoration is with the skills, access, spare parts, vendor support, and documentation you have today.
Score each axis on a local scale, then multiply the three values or apply a weighted formula. The mathematics matters less than consistency. A single WAN circuit should rank above an isolated marketing display because its failure can affect every dependent service at once.
Build the register around real dependencies
Include assets that teams often overlook. A useful first pass should contain:
- A single WAN ISP or circuit serving the whole venue.
- One RADIUS service or one identity-provider integration.
- One DNS resolver path.
- A single wireless controller or cloud management dependency.
- An intermediate distribution frame room with no generator coverage.
- UPS batteries that report status but have never been tested under meaningful load.
- A captive portal with no documented degraded mode.
- A switch stack whose uplinks share one physical route.
- A DHCP service with no tested recovery procedure.
The register should also record the service owner, technical owner, last failure date, current mitigation, test date, and next action. “Network team” isn't an owner. Name the person or team responsible for arranging the change and proving that it works.
Sample network risk register scoring
The following is a working template, not a claim about any particular estate. Use a consistent local scale for each axis and calculate the final score in the same way for every entry.
| Failure Scenario | Likelihood (1-5) | Blast Radius (1-5) | Recovery Pain (1-5) | Risk Score |
|---|---|---|---|---|
| Single WAN circuit | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
| Single RADIUS service | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
| Single DNS resolver path | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
| Single wireless controller | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
| Generator-less IDF room | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
| Unmonitored UPS batteries | Rate locally | Rate locally | Rate locally | Likelihood × blast radius × recovery pain |
Don't wait for a perfect register. A one-page list with credible owners is more useful than a polished risk system nobody updates. The immediate objective is prioritization. Rank the failures that can disable critical services, then use those results to set recovery targets and choose architecture.
Official US management information shows why structured advance planning matters in a different but related workforce context. Under the WARN Act, large-scale layoffs require advance notice, reinforcing the lesson for network leaders: formal planning exists because large operational changes are difficult to improvise. The same applies when a multi-site network loses a shared dependency.
Setting RTO and RPO Targets That Match Real Business Pain
RTO and RPO are useful only when business owners can understand them.
Recovery time objective, or RTO, is the maximum acceptable time a service can remain unavailable. Recovery point objective, or RPO, is the maximum acceptable loss of data, configuration, or session state since the last recoverable point. For a network, RPO may concern configuration, policy, device state, event records, or active authentication context rather than a traditional database transaction.
Translate both measures into operational consequences. Ask what stops first when the service fails. Does reception queue guests? Do cash registers stop accepting payments? Do clinicians lose access to electronic records? Does a property manager lose tenant access control? The service owner should state the business consequence, not just repeat an IT target.
Use service tiers rather than one property-wide promise
A practical service map separates critical access from services that can wait.
| Service Tier | Example Services | Target RTO | Target RPO | Architecture Implication |
|---|---|---|---|---|
| Tier 1 | Guest WiFi authentication, payment VLAN, clinical application access | Minutes, based on business tolerance | Minimal loss of policy and authentication state | Independent paths, rapid failover, resilient identity, tested power |
| Tier 2 | Staff WiFi, back-office systems, analytics synchronization | Around an hour, where the operation permits it | Recent configuration and service state | Warm standby, dual paths where justified, documented recovery |
| Tier 3 | Guest entertainment, marketing splash pages, non-critical reporting | Several hours may be acceptable | Backup-based recovery may be sufficient | Lower-cost standby or manual restoration |
These are planning examples, not universal service levels. Finance should validate the target using a simple loss model: estimated hourly revenue contribution, operational disruption, reputational exposure, and compliance impact, divided by the downtime the business can accept. Avoid false precision. A payment service may have no meaningful “average hour” because a short outage during a busy trading window can hurt more than a longer outage overnight.
RTO must also include detection and decision time. A failover that completes quickly after an engineer notices the fault may still miss the business target if monitoring takes too long to raise an alert. Include DNS propagation behavior, session reauthentication, device reconnection, firewall convergence, and human escalation in the recovery estimate.
RPO deserves the same discipline. If a configuration change made shortly before failure disappears, can the team recreate it? If guest sessions must reauthenticate, is that acceptable? If an identity directory is temporarily unavailable, can the access layer use a known-good policy without weakening security?
Aggressive RTO targets usually require active-active or geographically independent capacity. A more generous RTO can support a warm standby, documented restoration, or backup-based recovery. Don't copy an enterprise service level from a contract when the venue still relies on one ISP, one power feed, or one identity path. The architecture has to earn the target.
Choosing the Right Failover Architecture for Your Portfolio
Four patterns cover most real-world venue deployments. None is automatically correct. The right choice depends on downtime tolerance, portfolio size, operational skill, failure independence, and budget.
Active-active keeps two or more capable components serving traffic at the same time. Dual controllers or access clusters can share demand, and one side can continue when the other fails. This gives strong capacity during failure, but it creates more state synchronization, policy consistency, and split-brain risk. Use it when downtime is expensive and the team can monitor both sides properly.
Active-passive keeps a standby component ready to take over. It's easier to reason about than active-active, but promotion, state transfer, and detection can create a recovery gap. A hot standby is valuable only if it has current configuration, reachable dependencies, and a tested promotion process.
N+1 provides one spare capacity unit for a cluster. It's a sensible answer when a site can tolerate a component replacement but can't justify a fully duplicated environment. N+1 still leaves the property exposed to shared failures, such as a common power feed, common uplink, or bad configuration replicated across every unit.
Geographic redundancy places a complete service capability in another site or region. It addresses site loss, not just equipment failure, and it carries the highest capital and operational burden. It's appropriate for shared services supporting multiple properties or for organizations that can't accept a single building as a failure domain.
Failover architecture comparison
| Architecture | Cost | Complexity | Typical RTO | Best Fit |
|---|---|---|---|---|
| Active-active | High | High | Very short when correctly operated | Critical services, larger properties, teams able to manage synchronized systems |
| Active-passive | Medium to high | Medium | Short to moderate, depending on promotion | Sites needing a ready standby without serving traffic on both sides |
| N+1 | Medium | Medium | Moderate, depending on replacement and provisioning | Clusters where one component can cover a failed peer |
| Geographic redundancy | Highest | Highest | Short to extended, depending on routing and state | Multi-site operators and services exposed to full-site failure |
A hotel group with two properties may use active-active services between sites if the WAN, identity, DNS, power, and operational ownership are genuinely independent. A single retail store usually gets more value from a resilient firewall, segmented traffic, and LTE or 5G backup than from a second data center design it can't operate.
Use a direct decision shortcut. If staff resources are limited and the business can tolerate a measured recovery, choose active-passive or N+1. If critical transactions need continuity and the team can manage synchronization, choose active-active. If a whole site is the dominant risk, geographic redundancy is the answer. If the budget is tight, remove single-path dependencies in order of business impact rather than buying a duplicate of the most visible device.
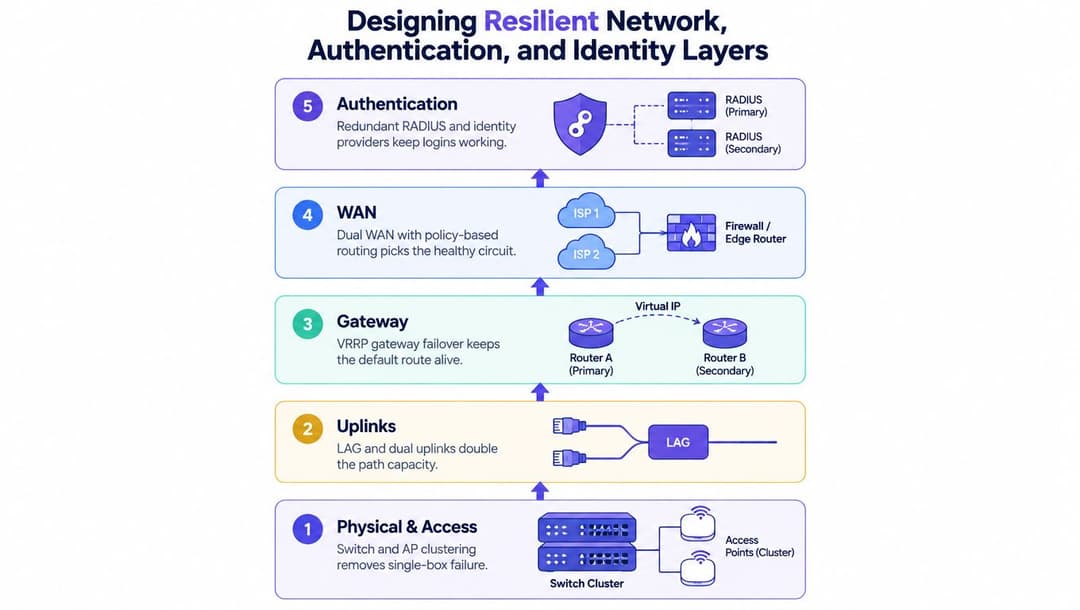
Designing Resilient Network, Authentication, and Identity Layers
Resilience fails at the weakest dependency. Build the stack from the physical layer upwards, and assign each layer an independent failure domain.
Start with access and uplinks
Use switch and access point clustering where the property requires it, but verify that cluster members don't share one failure domain. Two switches in the same rack may still depend on one power feed. Two uplinks may still follow one cable tray. Link aggregation can provide capacity and path resilience, while dual uplinks reduce dependence on a single port, module, or cable.
At the gateway, use VRRP or an equivalent virtual gateway mechanism so the default route can move between devices. Test stateful firewall failover rather than assuming that a floating gateway preserves active sessions. Some services reconnect cleanly. Others need explicit session handling.
WAN resilience should combine separate circuits with policy-based routing that recognizes health, not merely link state. A circuit can remain electrically up while losing the path to the applications that matter. LTE or 5G provides useful out-of-band access for management and a fallback path, but it needs its own coverage, power, data policy, and security controls.
Treat DNS and power as production dependencies
DNS is part of the user journey. Use deliberate TTL management, secondary resolution capability, and a split-horizon design where internal and external answers need to differ. Monitor resolution time and failure, not just whether a resolver process responds.
Power needs layers too. Combine UPS protection with a realistic PoE budget, separate feeds where the building supports them, and generator coverage for the rooms that host network dependencies. A UPS with a failed battery is not resilience. Neither is a generator that doesn't reach the access layer.
Protect authentication as carefully as connectivity
RADIUS should have independent service instances and a tested failover order. Captive portal behavior needs a defined degraded mode. Ask whether a user who has already authenticated can continue, whether a new user can complete the journey, and what happens when the identity provider is unreachable.
For staff access, a cloud-managed RADIUS service can reduce dependence on a single on-premises server, but it still needs multi-region availability, monitored endpoints, current certificates, and clear recovery ownership. Purple's Entra ID RADIUS service is one option for connecting network access with directory-based identity while keeping the authentication layer in the resilience conversation.
Every layer must fail independently. If both RADIUS nodes use the same virtual host, both DNS paths use the same resolver, and both WAN circuits enter through the same duct, the diagram is redundant but the property is not.
Testing, Monitoring, and Runbooks That Actually Catch Outages
Architecture on paper is not architecture in production. The only reliable way to validate a failover path is to exercise it under controlled conditions, observe the user experience, and fix what breaks.
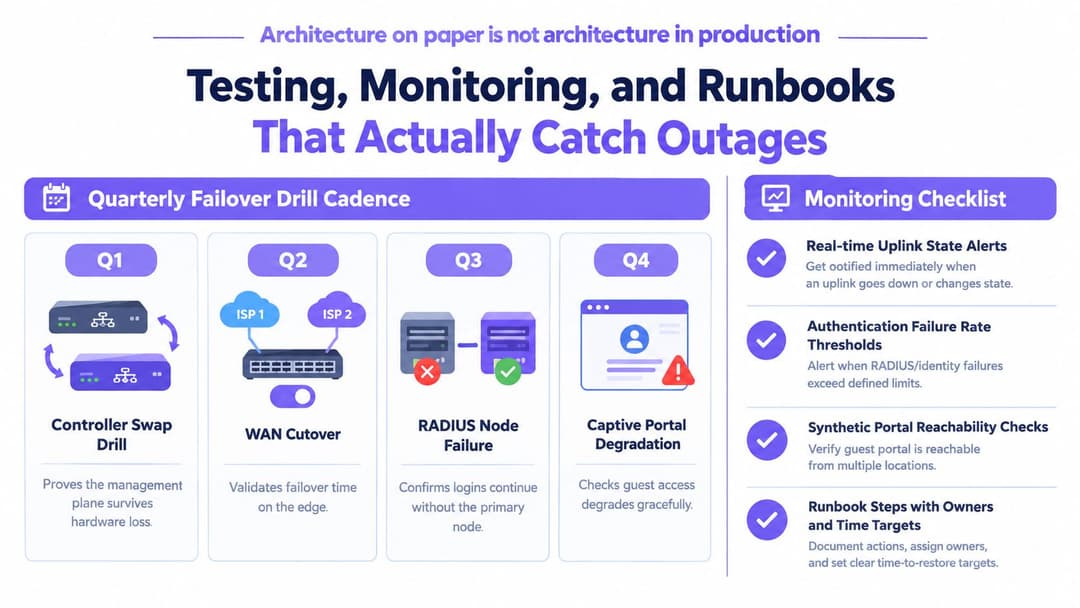
Run a quarterly drill program with a different failure focus each cycle:
- Controller swap: Prove that management and wireless service continue after the primary controller is removed.
- WAN cutover: Validate circuit detection, policy routing, firewall state, and application reachability.
- RADIUS node failure: Confirm that new logins and reauthentication use the secondary service.
- Captive portal degradation: Check that guest access fails safely and that existing users receive the intended experience.
Controlled chaos beats a tabletop exercise. On a low-risk night, disconnect a switch stack, disable a WAN path, or isolate a RADIUS node with an approved change record. Keep the test bounded, define a rollback, and make the service owner watch the business outcome rather than just the monitoring dashboard.
Monitor symptoms, not device vanity
Useful signals include:
- Controller reachability and cluster state.
- RADIUS response latency and authentication failure rate.
- DNS resolution time and failed lookups.
- Access point join state and client reassociation.
- Uplink utilization, errors, and path changes.
- Synthetic captive portal reachability.
- WAN health based on application probes, not interface status alone.
Set alert thresholds around customer impact. A small rise in authentication failures may indicate an identity outage before users call the help desk. An uplink at sustained capacity may be a precursor to degraded failover. Don't page engineers for every transient event. Do page them when several signals combine into a service symptom.
A runbook should contain a decision tree, named escalation owners, vendor contact order, access requirements, rollback steps, and time targets tied to the service RTO. Include screenshots or exact console locations where appropriate, but don't rely on tribal knowledge. After every drill, record detection time, decision time, recovery time, user impact, and the change required.
The Purple WiFi latency and jitter test can support practical validation of network quality, but no test replaces a real failover exercise. If you haven't failed a dependency on purpose, you haven't validated it.
Sector-Specific Considerations for Hospitality, Retail, Healthcare, and Multi-Tenant WiFi
The same resilience blueprint needs different priorities in different environments. Start by ranking services, then choose the identity and network controls that protect the highest-value user journey.
| Sector | Tier-1 Services | Recommended Failover Posture | Key Identity and Network Risk |
|---|---|---|---|
| Hospitality | Guest authentication, payment access, property systems, staff connectivity | Dual WAN, resilient RADIUS, tested captive portal recovery, protected power | A shared guest login or portal dependency can disrupt check-in and service delivery |
| Retail | POS traffic, payment services, store operations, staff access | Isolated VLANs, resilient edge, LTE or 5G backup, tested circuit cutover | Payment and operational traffic can compete with guest access without strict segmentation |
| Healthcare | Clinical WiFi, electronic records, telemetry, approved BYOD | Battery-backed network layers, resilient identity, controlled encryption recovery, audit-ready changes | An authentication or power failure can interrupt clinical workflows and create safety risk |
| Multi-family venues | Tenant access, common-area WiFi, building operations, staff services | Segmented SSIDs, tenant-aware policy, independent authentication domains, diverse paths | One operator's identity, DNS, or policy failure can cascade across tenants |
Hospitality operators should treat guest WiFi as an operational and commercial channel, not a courtesy service. Retail teams should keep payment paths isolated from guest traffic and verify that the backup circuit supports the actual transaction flow. Healthcare administrators need change records that stand up to audit, while also checking that battery-backed equipment covers the access path clinicians use.
For stadiums, Multi-Family buildings, coworking sites, and other multi-tenant venues, segmentation must continue into authentication and DNS. Separate SSIDs alone don't guarantee tenant isolation if policies, identity lookups, or management paths remain shared.
A sensible first move is a 30-day pilot inventory. Catalog access points, switches, controllers, WAN circuits, identity services, DNS, power, and owners across a representative property or venue. Then create a tiered SLA map for the sector, run one controlled failover, and use the results to fund the next risk reduction. Current workforce planning pressure also makes the people-risk angle important. The SHRM-aligned workforce outlooks show that layoffs and labor restructuring can hit unexpectedly. Fewer people means less tolerance for undocumented recovery work, so design runbooks and ownership before the next staffing change.
US employment guidelines under the WARN Act and related state "mini-WARN" laws make fragmented estates a timing and data problem. State regulations require strict notice periods for mass layoffs at a single site of employment. For network leaders, the analogous lesson is to map sites and dependencies precisely. A multi-site estate can't safely assume that separate buildings, circuits, or teams create separate failure domains without proving how traffic, identity, and operations connect.
Purple provides cloud-managed WiFi authentication and identity-based access, including RADIUS capability designed with redundant service paths, so it can form part of a resilience blueprint rather than leaving guest login as a hidden single point of failure. Review how Purple fits your network, identity, and failover requirements, then start with a property-level inventory and a controlled authentication drill.